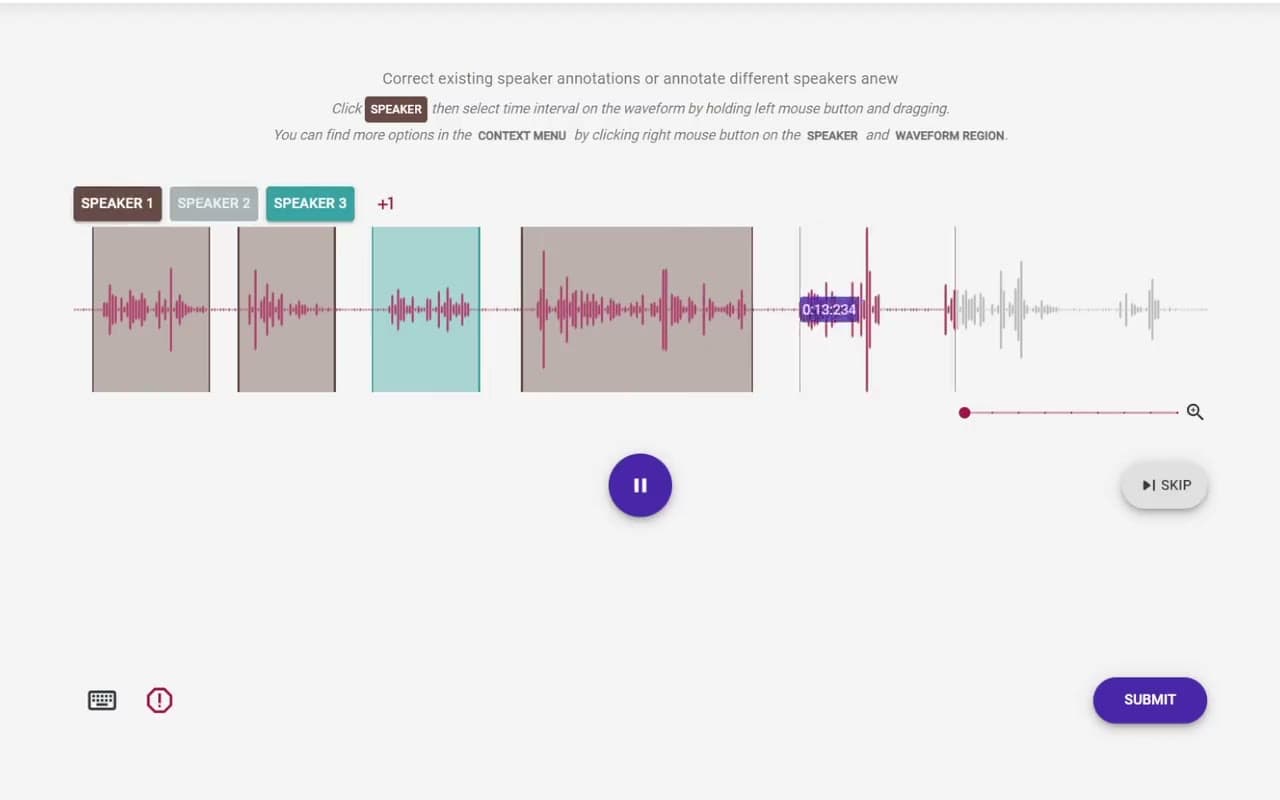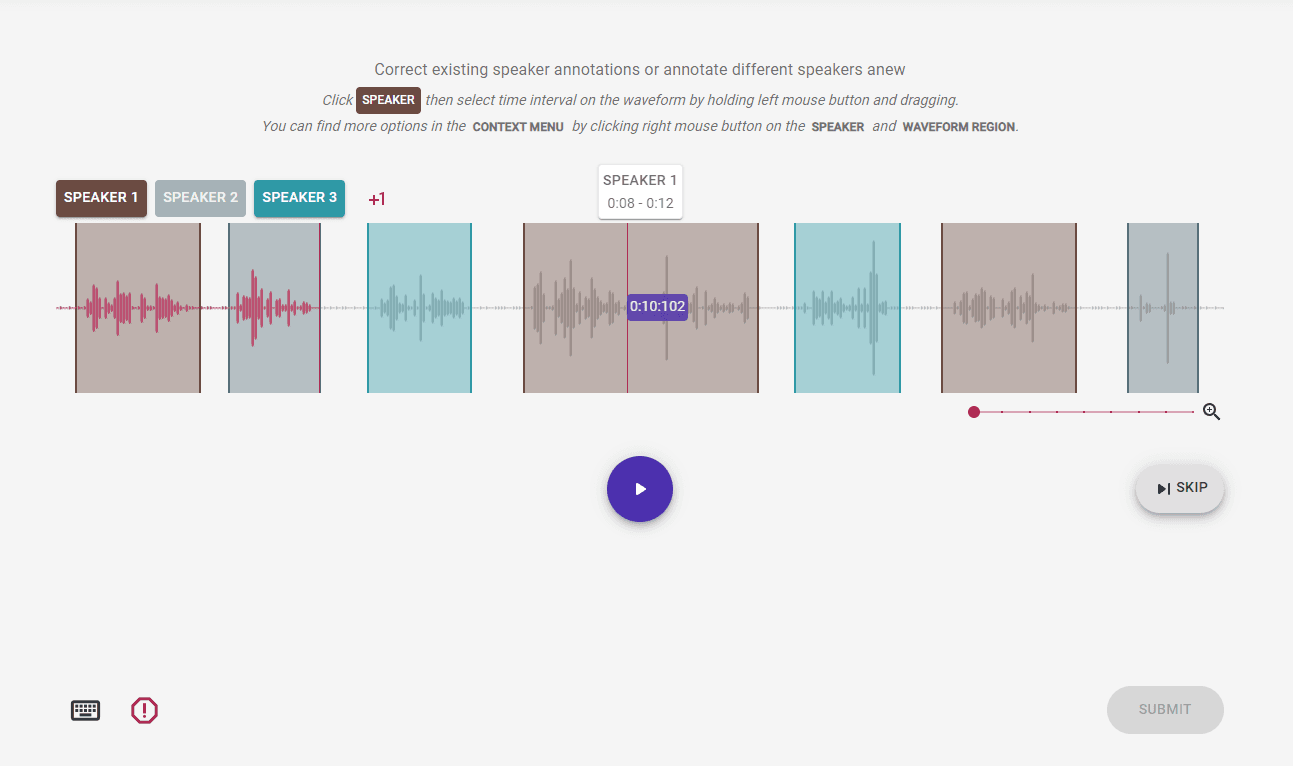
Recording and checking
Contributors read set sentences aloud in their own dialect, so the models learn how speech differs between regions.
A recording is not used straight away. Other contributors listen to it and check that the words match the text. They can:
- correct the text to match what was said,
- or reject the recording if it strays too far from the text or the sound is poor.
Only recordings that pass this check go into the training data.
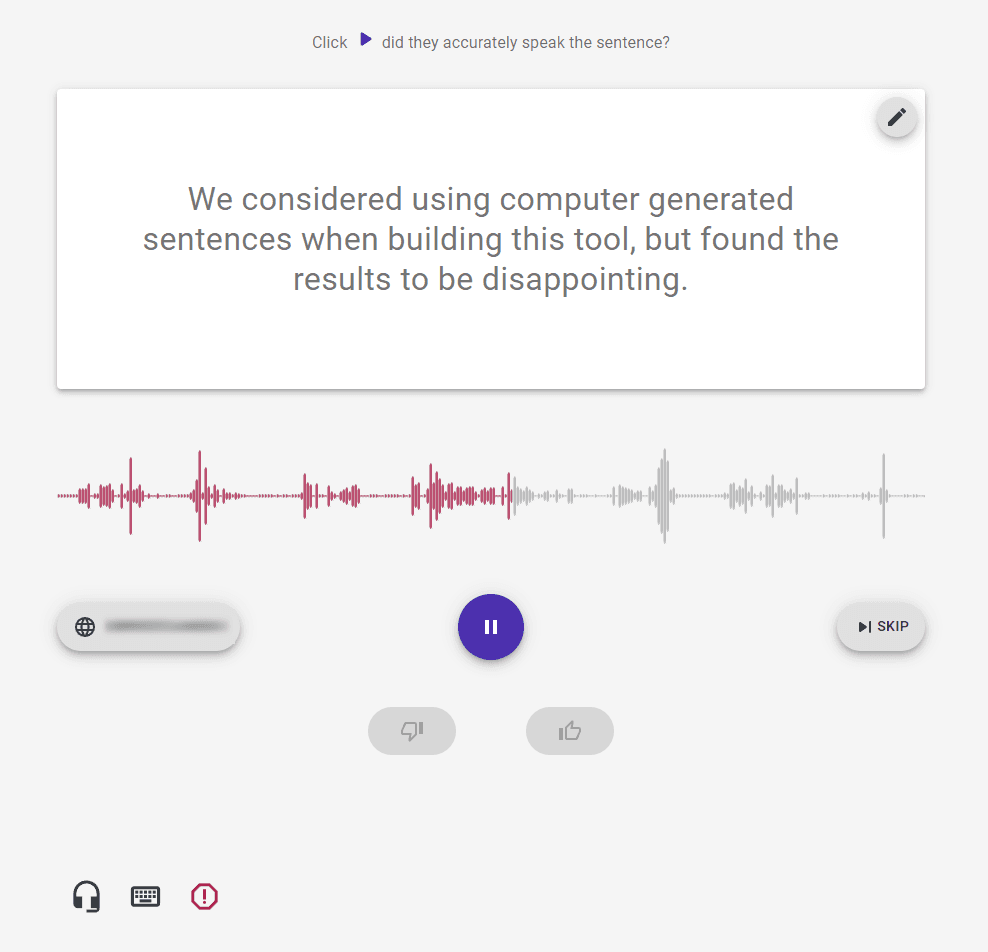
The question. Was the sentence spoken as written?
Sentence. What the contributor read. The pencil lets the reviewer correct the text to match the audio.
Recording. The audio, played back while it is checked.
Dialect. The region the contributor chose for their dialect, blurred here.
Verdict. Reject or accept the recording.